Claude Sonnet 5.5 vs Claude Opus 5.5: Which Claude Model Fits Your Work?
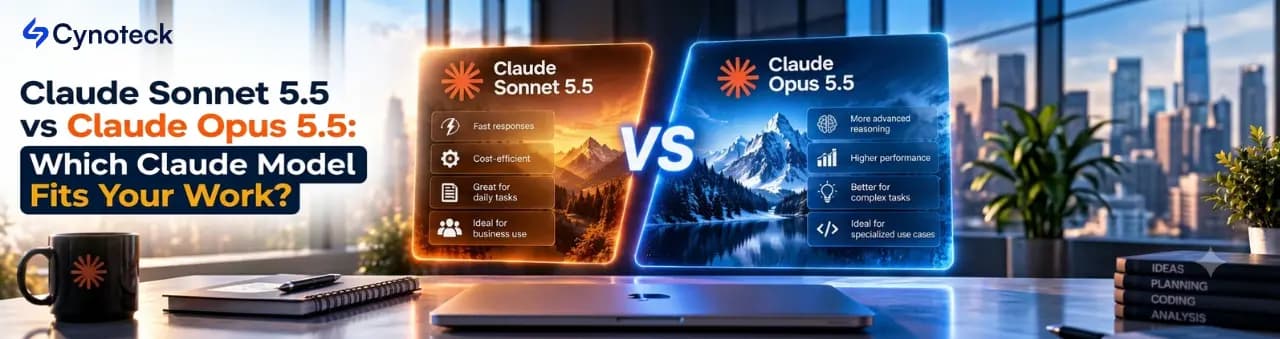
Claude Sonnet 5.5 vs Claude Opus 5.5 comes down to speed and cost versus depth and judgment. Opus 5.5 is Anthropic's model for extended, complex work where a wrong turn is expensive. Sonnet 5.5 streams faster, charges half the per-token price, and handles clearly defined everyday tasks very well. Both share a 1M-token context window, and independent testing puts them only two points apart on one major index.
Anthropic released Claude Opus 5.5 on September 22, 2026, and Claude Sonnet 5.5 six days later. Both belong to the Claude 5.5 family, so many people now ask which Claude model they should use. This guide explains each Claude model in plain language, compares them using Anthropic's own documentation, and shows when each one makes sense.
We checked every figure below against Anthropic's pages and independent benchmark data on October 9, 2026. Two things have changed since launch: Anthropic cut Sonnet 5.5's cache-read price on October 7, and it released Claude Haiku 5.5. Some comparisons online are already out of date. Prices and model lineups change quickly, so confirm the numbers on Anthropic's models overview before you budget.
Anthropic built Claude Opus 5.5 for complex work that needs careful judgment, while Claude Sonnet 5.5 is a quicker, cheaper option for clearly defined everyday tasks. Anthropic describes Sonnet 5.5 as a complement to Opus 5.5, not a replacement for it.
In practice, the two models overlap more than their names suggest. For example, Sonnet 5.5 matches or nearly matches Opus 5.5 on several benchmarks. Even so, Anthropic still rates Opus 5.5 as the clear leader on open-ended work that demands sustained judgment. The table below gives a quick comparison. After that, each section explains one row.
Factors | Claude Sonnet 5.5 | Claude Opus 5.5 |
|---|---|---|
How Anthropic pitches it | Its best blend of speed and intelligence | A model for extended agentic coding and knowledge work |
Release date | September 28, 2026 | September 22, 2026 |
Speed (per Anthropic's docs) | Fast | Moderate |
Price per million tokens (input/output) | $2 / $10 | $4 / $20 |
Cache reads per million tokens | $0.10 (cut from $0.20 on October 7) | $0.20 |
Context window | 1M tokens | 1M tokens |
Maximum output | 128K tokens | 128K tokens |
Reasoning mode | Adaptive, with up-front reasoning optional | Adaptive, and it cannot be switched off |
Starting effort level (API) | High | Medium |
Best for | Everyday coding, bug fixes, documents, slides, spreadsheets | Complex, open-ended, long-running, or high-stakes work |
API model ID |
|
|
Table 1. Claude Sonnet 5.5 vs Claude Opus 5.5 at a glance. Sources: Anthropic's models overview, launch pages, and release notes, checked October 9, 2026.
Claude AI is a family of large language models developed by Anthropic, and it now comes in four tiers. Haiku focuses on speed, Sonnet on balance, Opus on complex agentic work, and Fable on the hardest reasoning. In general, higher tiers cost more and respond more slowly, yet they handle harder problems.
Anthropic's models overview lists all four side by side. Claude Haiku 5.5, the newest member, launched on October 7, 2026, so most comparisons you find online predate it.
Model | Anthropic's positioning | Speed | Price per million tokens (input/output) |
|---|---|---|---|
Claude Haiku 5.5 | High-volume, latency-sensitive tasks such as classification, extraction, and routing | Fastest | From $0.10 / $0.50 |
Claude Sonnet 5.5 | Balances speed with intelligence | Fast | $2 / $10 |
Claude Opus 5.5 | Extended agentic coding and knowledge work | Moderate | $4 / $20 |
Claude Fable 5.1 | The hardest reasoning and extended agentic tasks | Slower | $10 / $50 |
Table 2. The Claude model lineup. Source: Anthropic's models overview, checked October 9, 2026.
Haiku and Fable sit at either end of the range. So Sonnet and Opus are the two models most teams compare first.
Claude Opus 5.5 is Anthropic's model for extended agentic coding and knowledge work. Agentic work means the model carries out multi-step tasks on its own, using tools such as a terminal or a code editor. Opus 5.5 also launched first in the Claude 5.5 line. According to Anthropic's launch page, it matches Claude Fable 5.1 on most tasks. Running it also costs 40% less than running Claude Opus 5. Anthropic adds that its responses arrive over 30% faster than Opus 5's.
Overall, Opus 5.5 is strongest on long, sprawling jobs such as codebase-wide migrations and audits. For example, Anthropic reports that one early tester had it audit and repair a codebase of 200,000 lines in less than three hours. The same job took Opus 5 over 20 hours. In an internal test, Opus 5.5 also translated the HAProxy load balancer from C into Rust in 9.5 hours. Fable 5.1 needed 12 hours, and Opus 5.5 cost 51% less.
The model also performs well on knowledge work. In one Anthropic test, Opus 5.5 wrote research reports under a strict rule: any invented figure or quote counted as a failure. Sixteen of its 18 reports cleared that bar. Meanwhile, Fable 5.1 and Opus 5 both failed to clear it in every attempt. Early testers reported similar gains. For instance, Clio left it running unattended across six repositories, and it stayed on task for more than 18 hours. Quantium reported that a complex coding job, which previously needed 38 prompts across four days, wrapped up in 11 prompts and three hours.
Communication improved as well. Anthropic says Opus 5.5 leads with the key point, avoids jargon, and respects the style rules you set. Teams that need more speed can also use a fast mode in Claude Code and on the Claude Platform. It runs up to 2.5 times faster and costs $8 for input and $40 for output per million tokens.
Claude Sonnet 5.5 is Anthropic's quicker, cheaper model for everyday work. It arrived second, after Opus 5.5, in the Claude 5.5 line. Anthropic's launch page says it runs over 30% faster than Claude Sonnet 5 and cuts cost per task by as much as 30% on most workloads. Notably, it keeps Sonnet 5's token prices, yet it usually finishes the same task with far fewer tokens.
Anthropic recommends Sonnet 5.5 for clearly defined everyday tasks, bug fixes, and polished documents, slides, and spreadsheets. In one internal test, Anthropic gave it a listed company's earnings reports, call transcripts, and a slide template. It then produced a 10-slide operating review, and two experts judged the first draft ready to send as is.
Early testers also noticed its efficiency. Base44 tested 118 real app builds. Sonnet 5.5's apps scored on par with Opus 5's, and they took 3.6 iterations on average versus 7.7 for Opus 5. Unity, meanwhile, reported that it completed 90% of the tasks in its multi-step Unity Editor and coding benchmark. Anthropic also notes that it is the first model in the Sonnet line to finish Pokémon Red from screenshots alone, a sign of better long-task and image skills.
Since launch, Anthropic has halved Sonnet 5.5's cache-read price to $0.10 per million tokens. As a result, Anthropic says, Sonnet 5.5 now costs about 20% less on most agentic workloads. The launch page still lists the old $0.20 price, so check the release notes when you compare sources.
Opus 5.5 leads Sonnet 5.5 on most benchmarks, usually by about three points or less, while Sonnet 5.5 leads on Terminal-Bench 4.0. All the figures below come from Anthropic's launch pages, so they are vendor-reported results and not independent tests.
Benchmark | What it measures | Sonnet 5.5 | Opus 5.5 | Result |
|---|---|---|---|---|
Terminal-Bench 4.0 | Complex, multi-step professional tasks in a command-line interface | 70.6% | 66.4% | Sonnet ahead by 4.2 |
FrontierCode 1.1 | Whether a coding agent's changes would pass review and get merged | 52.1% (X high effort) | 54.4% | Opus ahead by 2.3 |
CursorBench 4.0 | Ambiguous, multi-file coding tasks from real Cursor sessions | 55.5% | 57.8% | Opus ahead by 2.3 |
GDPval-AA v2.1 | Real-world work across 44 occupations (Elo score) | 1844 | 1846 | Nearly level (2 points) |
AA-Briefcase v1.1 | Long-horizon knowledge work (Elo score) | 1811 | 1822 | Opus ahead by 11 |
Humanity's Last Exam (with tools) | Multidisciplinary reasoning | 64.5% | 67.7% | Opus ahead by 3.2 |
OSWorld 2.1 (partial credit) | Operating a real computer | 80.1% | 81.8% | Opus ahead by 1.7 |
Chartography (no tools) | Visual chart recognition | 61.6% | 64.4% | Opus ahead by 2.8 |
Table 3. Benchmarks reported on Anthropic's launch pages. Opus 5.5's Terminal-Bench score is at Xhigh effort, its highest. Sonnet 5.5 scored 46.2% on FrontierCode at Max effort, below its Xhigh score.
Three patterns stand out. First, the gaps are small, and the two models finish nearly level on GDPval-AA. Second, Sonnet 5.5's lead on Terminal-Bench shows that the cheaper model can win on certain agentic tasks. Third, Anthropic cautions that benchmark scores show just part of a model's ability. Its Sonnet page adds that Opus 5.5 is still the clear pick when work is complex, open-ended, and depends on sustained judgment. Its Opus page adds that, at this capability level, small benchmark gaps predict real-world differences less reliably.
So treat the table as a starting point, and check who ran each test. The next section shows what an independent firm found.
Independent testing by Artificial Analysis puts the two models two points apart on its Intelligence Index: 58 for Opus 5.5 and 56 for Sonnet 5.5, both at Max effort. That firm tests every model under identical conditions. Its index combines ten tests, including GDPval-AA, AA-Briefcase, Terminal-Bench 4.0, SciCode, and Humanity's Last Exam.
Measure (Max effort) | Sonnet 5.5 | Opus 5.5 | Result |
|---|---|---|---|
Intelligence Index | 56 | 58 | Opus ahead by 2 |
GDPval-AA v2.1 (Elo) | 1838 | 1866 | Opus ahead by 28 |
AA-Briefcase v1.1 (Elo) | 1823 | 1807 | Sonnet ahead by 16 |
AutomationBench-AA | 71.8% | 69.5% | Sonnet ahead by 2.3 |
Terminal-Bench 4.0 | 63.6% | 59.6% | Sonnet ahead by 4.0 |
SciCode | 61.0% | 66.9% | Opus ahead by 5.9 |
Humanity's Last Exam | 55.0% | 61.4% | Opus ahead by 6.4 |
AA-Omniscience Index | 32 | 46 | Opus ahead by 14 |
Table 4. Independent benchmark results at Max effort with Anthropic's default fallback, as published on October 9, 2026.
Three points stand out. First, the independent run agrees with Anthropic on direction. Sonnet 5.5 leads on Terminal-Bench 4.0, while Opus 5.5 leads on most knowledge and reasoning tests. Second, the widest gap appears on AA-Omniscience, which the testers describe as a knowledge and hallucination benchmark that rewards accuracy and punishes bad guesses. Opus 5.5 scores 46 there and Sonnet 5.5 scores 32. That gap matters most if your application answers factual questions from the model's own knowledge.
Third, the numbers differ from Anthropic's launch table. AA-Briefcase flips in Sonnet's favor, and the GDPval-AA gap widens. Anthropic notes that the independent testers ran their first tests on an early, pre-launch version of Sonnet 5.5 with a bug that could degrade some responses, and that Anthropic has since fixed the bug. So no single score tells the whole story. The best test is still your own work, run on both models, with your own definition of a good result.
Per token, Claude Sonnet 5.5 charges half of what Claude Opus 5.5 charges. Input runs $2 versus $4 per million tokens, and output runs $10 versus $20. Before you compare prices, it helps to know what a token is. A token is a small chunk of text, roughly a short word or part of a word. Every request counts the tokens you send, called input, and the tokens Claude writes back, called output.
Token type (price per million) | Sonnet 5.5 | Opus 5.5 |
|---|---|---|
Input you send | $2 | $4 |
Output Claude writes | $10 | $20 |
Cache reads (reused text) | $0.10 | $0.20 |
Cache writes (storing text) | $2.50 | $5 |
Fast mode (input/output) | Not listed | $8 / $40 |
Table 5. Claude API list prices per million tokens. Sources: Anthropic's launch pages and release notes (Sonnet 5.5 cache reads cut to $0.10 on October 7, 2026).
Cache reads deserve attention. Prompt caching lets you reuse repeated text at a lower price, because the model does not process it from scratch. Anthropic notes that cache reads make up the majority of the cost in agentic and coding work, so that price matters more than it first appears.
For example, suppose a task sends 100,000 input tokens and returns 10,000 output tokens. At list prices, Sonnet 5.5 costs about $0.30: $0.20 for input plus $0.10 for output. Opus 5.5 costs about $0.60: $0.40 plus $0.20. However, this example uses identical token counts for both models. In real use, the counts differ because each model decides how long to think and how many steps to take. Anthropic reports that both new models use fewer tokens than their predecessors. So measure the cost of a finished task on your own work, and do not rely on price per token alone.
No, Sonnet 5.5 is not always cheaper per task. In the independent data, it costs less at every effort level, but scores lower at each level, and Opus 5.5 reaches the same score for less at the top of the range.
The clearest way to see this is to rank every configuration by score. The list below puts all ten Sonnet 5.5 and Opus 5.5 settings in one order, so you can read across models at the same quality level.
Rank by score | Model and effort | Score | Cost per task |
|---|---|---|---|
1 | Opus 5.5, Max | 58 | $5.98 |
2 | Opus 5.5, Xhigh | 56 | $3.46 |
2 | Sonnet 5.5, Max | 56 | $5.46 |
4 | Opus 5.5, High | 54 | $1.82 |
5 | Sonnet 5.5, Xhigh | 52 | $2.01 |
6 | Opus 5.5, Medium | 51 | $1.34 |
7 | Sonnet 5.5, High | 47 | $0.88 |
8 | Opus 5.5, Low | 42 | $0.55 |
9 | Sonnet 5.5, Medium | 41 | $0.48 |
10 | Sonnet 5.5, Low | 36 | $0.35 |
Table 6. All ten configurations ranked by independent Intelligence Index score, with cost per Intelligence Index task, as published on October 9, 2026. These figures come from a test workload, so they will not match a real invoice.
Reading down the list reveals three things. At a score of 56, Opus 5.5 at Xhigh costs $3.46, while Sonnet 5.5 needs Max and costs $5.46. Opus 5.5 at High also beats Sonnet 5.5 at Xhigh on both counts, with a score of 54 for $1.82 against 52 for $2.01. Near the bottom, though, the two are almost interchangeable: Sonnet 5.5 at Medium (41) costs $0.48, and Opus 5.5 at Low (42) costs $0.55.
The numbers also shift whenever prices change. The independent firm calculates cost from token prices, including cache prices, so the $5.46 figure for Sonnet 5.5 at Max reflects Anthropic's October 7 cache-read cut.
Real workloads can differ from either benchmark. Thinking tokens count toward the output limit, so Anthropic recommends a large max_tokens value, and it suggests 128,000 for agentic coding on Sonnet 5.5. Settings like this change both cost and results, which is why the test steps later in this guide matter.
Speed deserves the same caution. At Max effort, the independent firm clocked Sonnet 5.5 at 138 tokens per second and Opus 5.5 at 97. Yet a full task took about 904 seconds on Sonnet 5.5 and about 775 on Opus 5.5, because total time depends on how long each model thinks. Streaming faster does not mean finishing sooner.
The effort setting controls how many tokens Claude spends on a response, so it lets you trade thoroughness against cost and speed. Anthropic's effort documentation describes five levels, and it describes effort as a signal about behavior, not a hard cap on tokens.
Level | What Anthropic says it is for |
|---|---|
Low | Simple jobs where speed and low cost matter most, such as subagents |
Medium | Agentic work that needs speed, cost, and quality in balance |
High | Complex reasoning, difficult coding problems, and agentic tasks |
Xhigh | Long-horizon agentic and coding work, over 30 minutes, with large token budgets |
Max | Tasks that need the deepest possible reasoning, with no limit on token spending |
Table 7. Effort levels and typical uses. Source: Anthropic's effort documentation, checked October 9, 2026.
Defaults differ between the two models, and that affects any side-by-side test. Inside Claude Code and the Claude apps, Sonnet 5.5 starts at Medium. On the API, however, Sonnet 5.5 defaults to High, while Opus 5.5 defaults to Medium. A test that uses default settings therefore does not compare equal effort.
Anthropic also gives model-specific starting points. For Sonnet 5.5, Anthropic suggests High as the opening level, except for agentic or speed-sensitive work. For agentic coding with clear specifications, begin at Medium and step up to High as tasks get harder or longer. For chat and other speed-sensitive uses, begin at Medium or Low. Reserve Xhigh and Max for cases where your own tests show a quality gain. For Opus 5.5, Medium is the default, and Anthropic advises testing each effort level against your own evaluations instead of reusing settings from an older model.
Anthropic's charts show why this matters. Its charts show Sonnet 5.5 at Low or Medium effort topping Sonnet 5's best result on several benchmarks while costing roughly a tenth as much per task. Anthropic says Sonnet 5.5 pairs best with Opus 5.5 at lower effort levels, where each task costs less. Turned up, it can match Opus on several tests at about the same cost. Higher is not always better, though. On FrontierCode, Sonnet 5.5 scored lower at Max than at Xhigh, because at Max it more often ran a code-review routine that timed out or added unrelated edits. Finally, thinking counts toward the output limit even when it is not shown, so set max_tokens with room for both thinking and the reply.
Sonnet 5.5 and Opus 5.5 match on context window, output limit, knowledge cutoff, and where you can use them. The context window is the amount of text a model can consider at once. Both offer 1M tokens, which is large enough for long documents and big codebases.
Here is what the two models share, according to Anthropic's documentation:
A 1M-token context window and a 128K-token maximum output.
A reliable knowledge cutoff of June 2026.
Text and image input, text output, multilingual capabilities, vision, and tool use.
Availability on Google Cloud, Amazon Bedrock, Microsoft Foundry, Claude Platform on AWS, and the Claude API.
Zero data retention, which Anthropic offers for both models.
No support for forced tool use, because the docs list that setting as an error for both.
One technical difference is worth knowing if you build with the API. Opus 5.5 always uses adaptive thinking, so you cannot disable it. Sonnet 5.5, however, lets you switch off up-front thinking through a setting called between_tools. Anthropic's Opus 5.5 notes and Sonnet 5.5 notes cover the migration details.
Yes, but the API drops any reasoning the new model cannot read, so it is safer to escalate from Sonnet 5.5 to Opus 5.5 than to move the other way. Anthropic's docs say each reasoning block carries a label naming the model that wrote it, and that each model can read only some other models' blocks.
Across the Claude API and on Google Cloud, Opus 5.5 reads Sonnet 5.5's thinking blocks, so a conversation that moves up from Sonnet to Opus keeps its reasoning. Sonnet 5.5, however, does not read Opus 5.5's blocks. A conversation that moves down from Opus to Sonnet therefore continues without the earlier reasoning. In both directions the request still succeeds, and Anthropic does not bill the dropped blocks. Other platforms can behave differently, so check the docs for yours.
This rule shapes how you combine the models. If a task starts on Sonnet 5.5 and proves harder than expected, escalating to Opus 5.5 preserves the work so far. If you want Opus to plan and Sonnet to execute, hand over a written plan in a new session, instead of switching inside one conversation.
Both Claude models ship with safeguards, and Anthropic reports that Opus 5.5 scores slightly better overall on its alignment audit. Anthropic also admits that no evaluation suite reliably catches every failure, which is why it pairs its testing with safeguards.
Area | Claude Sonnet 5.5 | Claude Opus 5.5 |
|---|---|---|
Alignment audit | Equal to or better than Sonnet 5 on most measures; Opus 5.5 scores slightly higher overall | Anthropic's strongest-performing model on its automated behavioral audit |
Containment | Close to Opus 5.5, and the model least inclined, of any Anthropic model, to test the edges of its containers | Tried to get around its boundaries roughly 85% less often, compared with Opus 5 and Claude Mythos 5.1 |
Cybersecurity safeguards | Higher-risk tasks visibly fall back to Sonnet 5 | Most cybersecurity tasks are re-routed to Opus 4.8 |
Biology safeguards | Same as Sonnet 5 | Same as Fable 5.1; vetted organizations can enroll in the Life Sciences Verification Program |
Anti-distillation | Classifiers block attempts to extract its reasoning, and preserved thinking is expanded | Preserved thinking covers API accounts opened from August 31, 2026 onward |
Compliance extras | Zero data retention available | Zero data retention available; watermarking measures for the EU AI Act |
Table 8. Safeguards and safety results reported by Anthropic on its launch pages. Anthropic admits its evaluations cannot catch every failure.
For most users, these safeguards change little. Both models still help with routine software development, including finding and fixing bugs. The safeguards apply to a small group of high-risk requests, mainly in cybersecurity and biology.
Choose Claude Sonnet 5.5 for clear, repeatable tasks that are easy to check, and choose Claude Opus 5.5 for ambiguous, long-running, or high-stakes work. In the Claude Sonnet 5.5 vs Claude Opus 5.5 decision, Anthropic's own guidance adds a useful nuance. Its docs say to start with Opus 5.5 for most workloads when you are unsure. They add that Fable 5.1 suits demanding reasoning, or cases where Opus 5.5 at higher effort still falls short. Its Sonnet launch page, meanwhile, presents Sonnet 5.5 as the quicker, cheaper choice for everyday work.
Both pieces of advice fit together. Pick Sonnet if you can define the task and verify the result. Pick Opus if you cannot, or if a mistake would be expensive.
Your task | Better pick | Why |
|---|---|---|
Fixing bugs and scoped feature changes | Sonnet 5.5 | Anthropic names bug fixing as a strength, and its CursorBench score sits roughly two points below Opus 5.5 |
Creating documents, slides, and spreadsheets | Sonnet 5.5 | Anthropic highlights polished documents and decks that need minimal editing |
Everyday drafting, summarizing, and chat | Sonnet 5.5 | It is fast and charges half the per-token price |
High-volume, repeatable agent jobs | Sonnet 5.5, or Haiku 5.5 for simple routing | Lower cost per task at lower effort settings |
Codebase-wide migrations and audits | Opus 5.5 | Anthropic calls these a particular strength |
Long investigations with an unclear path | Opus 5.5 | Anthropic rates Opus ahead on open-ended work |
High-stakes research, finance, or legal analysis | Opus 5.5 | Our view: when a wrong answer costs more than the price gap, the stronger model pays for itself |
Answers that rely on the model's own factual knowledge | Opus 5.5 | It scores 46 versus 32 on AA-Omniscience in the independent data |
The highest score for the lowest cost per task | Opus 5.5 at Medium to Xhigh | It reaches scores of 51 to 56 for less than Sonnet 5.5 needs at higher effort |
You are unsure, and mistakes are costly | Opus 5.5 | Anthropic's docs suggest starting with Opus when unsure |
Classification, extraction, and routing at scale | Haiku 5.5 | Fastest and lowest cost, per Anthropic's docs |
The hardest reasoning, where Opus at high effort falls short | Fable 5.1 | Anthropic positions it for the most demanding work |
Table 9. Suggested model by task. Sources: Anthropic's launch pages and docs, and independent benchmark data. The pairings reflect our reading of that evidence.
Many teams combine Claude models. One early tester at Creator described this pairing. When Opus 5.5 sets a game's architecture, they feel confident letting Sonnet 5.5 implement it. Anthropic also says Haiku 5.5 works well beside Opus and Sonnet as a helper agent in coding workflows. A workable split follows from that: Opus decides the approach, Sonnet carries it out, and Haiku takes the minor, repeatable chores. Run those roles in separate sessions, though, because moving down from Opus to Sonnet inside one conversation drops Opus's reasoning.
Run both models on the same real tasks, at several effort levels, and compare the cost of each accepted result, not the price per token. Published scores, whether from a vendor or an independent lab, measure someone else's workload, so only your own test can settle the question.
Collect a sample of real tasks, and include a few hard ones. Easy tasks alone cannot show whether the pricier model earns its place.
Define success before you run anything. Use tests, a checklist, or a review rubric, so every result is either accepted or rejected.
Run an effort sweep on both models. Anthropic recommends this over reusing settings from an older model, and it keeps the comparison fair.
Record every cost, including failed attempts, retries, and thinking tokens. Then divide total spend by the number of accepted results.
Watch time and failure modes, such as output limits and timeouts, along with cost.
Pick a model per task type, and run the test again whenever prices or models change.
Here is a simple illustration. Suppose Sonnet 5.5 spends $30 across 100 tasks and 75 pass, which is $0.40 per accepted task. Opus 5.5 spends $45 across the same 100 tasks and all 100 pass, which is $0.45 per accepted task. The pricier model costs only $0.05 more per accepted result, and it leaves no failed tasks to rework. These numbers are illustrative, not measurements.
The Claude Sonnet 5.5 vs Claude Opus 5.5 choice is one decision in a larger design. The right model also depends on your data, your budget, and how much a wrong answer costs your business.
Cynoteck's teams work with large language models including Claude, GPT, Gemini, and LLaMA. They choose the right one based on cost, data sensitivity, and accuracy needs. If you plan to build agents or chatbots, explore our agentic AI development services and AI chatbot development services. You can also talk to our AI consulting and development team about the best starting point.
Neither is better in every case. Opus 5.5 leads on most benchmarks and on complex, open-ended work, and independent testing puts it two points ahead. Sonnet 5.5, however, leads on Terminal-Bench 4.0 in both Anthropic's and the independent runs, generates more tokens per second, and charges half the per-token price.
Not always. In the independent data, Sonnet 5.5 costs less at every effort level but scores lower at each level. At a score of 56, Opus 5.5 at Xhigh costs $3.46 per task, while Sonnet 5.5 at Max costs $5.46.
It is worth it if the work is complex, long-running, or costly to get wrong. For routine tasks, however, Sonnet 5.5 delivers close results at a lower price. Anthropic also notes that Opus 5.5 is about 40% cheaper to run than Opus 5 on typical workloads.
Anthropic's docs rate Sonnet 5.5 as fast and Opus 5.5 as moderate, and Sonnet 5.5 generates more tokens per second. Time per task, however, depends on how long each model thinks. Opus 5.5 also offers a fast mode that runs up to 2.5 times faster, at a higher price.
It charges half the per-token price: $2 and $10 per million input and output tokens, versus $4 and $20 for Opus 5.5. Cache reads and cache writes are half price too. The real cost of a task also depends on how many tokens each model uses.
Opus 5.5. On the independent AA-Omniscience Index, which rewards accuracy and punishes bad guesses, Opus 5.5 scores 46 and Sonnet 5.5 scores 32. Check any model's answers against sources when facts matter.
For Sonnet 5.5, Anthropic's docs point to High as the default starting level. Agentic coding with clear specs can begin at Medium, and chat can begin at Medium or Low. Opus 5.5 defaults to Medium. Test several levels on your own tasks.
Yes. Across the Claude API and on Google Cloud, Opus 5.5 reads Sonnet 5.5's reasoning, so you keep it. Moving the other way drops Opus's reasoning, because Sonnet 5.5 cannot read it. Anthropic does not bill the dropped blocks.
Yes. Both offer a 1M-token context window and a 128K-token maximum output.
Opus is the higher tier, built for complex agentic work and careful judgment. Sonnet is the balanced tier, built for speed and everyday tasks. Haiku sits below Sonnet for high-volume work, and Fable sits above Opus for the most demanding reasoning.
Yes, especially for bug fixes and well-scoped tasks. In Anthropic's results, its Terminal-Bench 4.0 score is 70.6% and its CursorBench 4.0 score is 55.5%. For very large migrations and audits, Anthropic points to Opus 5.5.
For everyday chat in the Claude apps, Sonnet 5.5 is a sensible starting point if your plan includes it, because it is fast and handles routine tasks well. Switch to Opus 5.5 when a task is complex or needs deeper judgment. If you build with the API and are unsure, Anthropic's docs suggest starting with Opus 5.5.
In the Claude API, use `claude-sonnet-5-5` for Sonnet 5.5 and `claude-opus-5-5` for Opus 5.5.
Yes. A common approach is to let Opus 5.5 plan and make the hard decisions, and let Sonnet 5.5 carry out the well-defined steps. Use separate sessions or a written handoff, because moving down from Opus to Sonnet in one conversation drops Opus's reasoning. Haiku 5.5 can handle small, repetitive subtasks.
It is Anthropic's fastest and lowest-cost Claude model, launched on October 7, 2026. Anthropic describes it as built for high-volume, cost-sensitive tasks such as summaries, classification, and database queries.
Every figure comes from Anthropic's launch pages and documentation, or from the independent benchmark data described above. We checked them on October 9, 2026. Prices, scores, and model lineups change quickly, so confirm the latest values on the Anthropic pages linked above before you budget.
What is Artificial Intelligence? Artificial intelligence (AI) is intelligence demonstrated by machines, which makes it possible for machines to learn from experience, adjust to new inputs and perform human-like tasks.
We are more than just developers and consultants—we are your partners in navigating the digital landscape. Let us be the engine behind your next big success while you focus on your core vision.
Explore Opportunities!
 What Al Services Does a Business Actually Need in 2026.webp)